When: Monday October 26th 2026, 15:05-16:50
Overview
How do we learn a game when nobody tells us the rules, and can AI help explain the brain activity behind that learning? This hands-on tutorial examines how frontier large reasoning models (LRMs) learn new games, and how their behavior and internal representations align with those of human players and their brain activity. Yann Harel will lead the session in person, and Csaba Botos will join online.
A video capsule giving an overview is available in the Materials section below.
Instructors
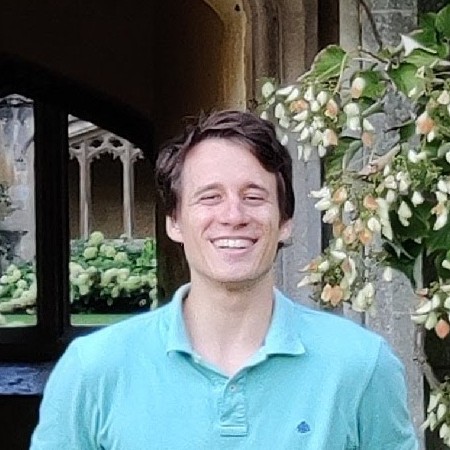
Csaba Botos
Google DeepMind
Yann Harel
Boston College
Csaba Botos is a senior research scientist at Google DeepMind. He completed his DPhil in Engineering Science at the University of Oxford with Philip Torr and Adel Bibi. He led “Reason to Play”, a study of the behavioral and brain alignment between frontier large reasoning models and human game learners.
Yann Harel is a postdoctoral researcher at Boston College, working at the intersection of brain imaging, cognitive neuroscience and interactive environments. He contributed to the Courtois NeuroMod project, where he helped design and build naturalistic neuroimaging datasets linking real-time videogame behavior with fMRI, physiological and eye-tracking data. His research draws on large-scale open datasets, electrophysiology (EEG, MEG) and fMRI to study learning, attention and flow, as well as practical aspects of human-AI alignment.
Objectives
Discover how frontier large reasoning models learn to play new games.
Compare the learning curves of large reasoning models and human players.
Learn how to assess the alignment between large reasoning models, human behavior and brain activity.